GPT-6 Astra vs Claude Fable 5.1: Which AI Model Should You Choose?
GPT-6 Astra vs Claude Fable 5.1: Which AI Model Win?
Introduction:
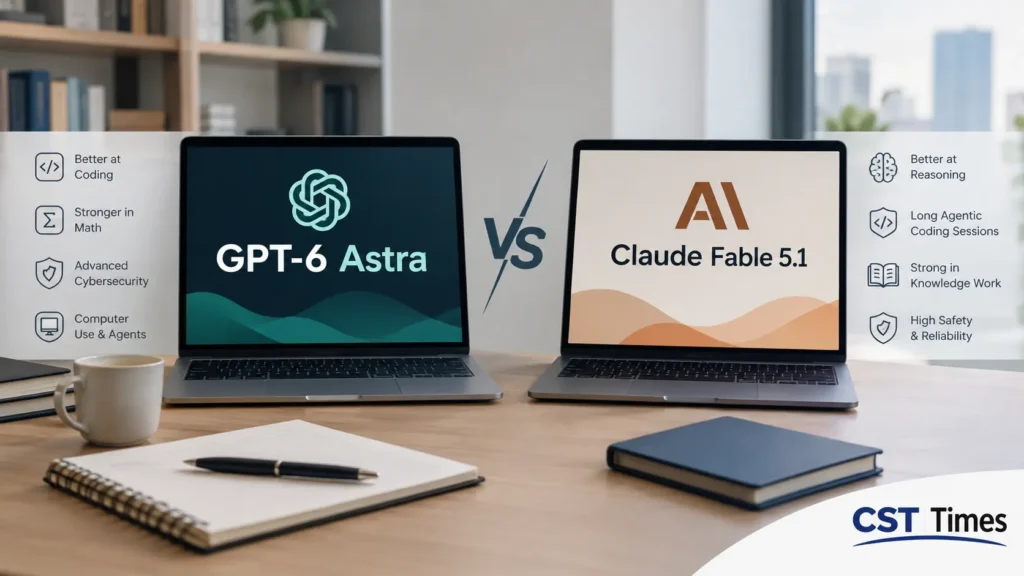
GPT-6 Astra is OpenAI’s newest flagship model, and Claude Fable 5.1 is Anthropic’s most advanced model for coding and knowledge work. The two launched days apart in early September 2026, and neither company benchmarked directly against the other. Astra leads on computer use, mathematics, and cybersecurity; independent testing shows Fable 5.1 ahead on general reasoning and long agentic coding sessions. Here’s how these two artificial intelligence systems compare on pricing, context window, benchmarks, and safety.
Table of Contents
ToggleKey Takeaways
- Claude Fable 5.1 launched September 1, 2026; GPT-6 Astra followed two days later, on September 3.
- Both charge $10 per million input tokens and $50 per million output tokens — the headline price is identical.
- On OpenAI’s own launch-day benchmark table, Astra leads Fable 5.1 on most rows, including math, science, and computer-use tasks.
- On Artificial Analysis’s independent Intelligence Index, Fable 5.1 currently scores higher than Astra.
- Astra’s cached input costs four times more than Fable 5.1’s ($1 vs. $0.25 per million tokens), which matters most for long, context-heavy agent sessions.
- Astra is the first model OpenAI has classified as “Critical” for cyber capability; Anthropic keeps Fable 5.1’s least-restricted version, Claude Mythos 5.1, limited to vetted professionals.
Table of Contents
- What is GPT-6 Astra?
- What is Claude Fable 5.1?
- Quick Comparison Table
- Pricing: Same Headline Rate, Different Real Cost
- Benchmarks: Who Actually Wins?
- Safety and Alignment Approach
- Which One Should You Actually Use?
- Final Thoughts
- FAQs
What is GPT-6 Astra?
GPT-6 Astra is OpenAI’s newest flagship model, released on September 3, 2026. OpenAI describes it as its most intelligent and aligned model yet, built for computer use, web browsing, software engineering, cybersecurity, science, and general professional work. It rolled out first to a limited set of organizations, with access expanding over subsequent days to ChatGPT Plus, Pro, Business, and Enterprise users, plus the OpenAI API, Microsoft Azure, and AWS Bedrock.
OpenAI’s own results show Astra scoring 97.6% on FrontierMath Tier 4, 99.9% on ARC-AGI-3, and 100% on ExploitBench, a cybersecurity evaluation. That last score is notable: Astra is the first model OpenAI has classified as reaching “Critical” cyber capability under its internal risk framework, meaning it can find and exploit previously unknown security flaws without a human guiding every step.
What is Claude Fable 5.1?
Claude Fable 5.1 is Anthropic’s newest flagship model, released on September 1, 2026, two days before Astra. Anthropic pitches it as its most advanced model for coding and knowledge work, built for long, unattended agent sessions, deep research, and complex software projects. It shares its underlying weights with Claude Mythos 5.1, a version with lighter safeguards reserved for vetted cybersecurity and life-science researchers through Anthropic’s trusted access programs.
Fable 5.1 is available on Claude.ai, the Claude API, Amazon Web Services, Google Cloud, and Microsoft Foundry, across the Pro, Max, Team, and Enterprise plans. It isn’t available on Claude’s free tier.
Quick Comparison Table
GPT-6 Astra | Claude Fable 5.1 | |
|---|---|---|
| Developer | OpenAI | Anthropic |
| Release date | September 3, 2026 | September 1, 2026 |
| Context window | ~1.05 million tokens | 1 million tokens |
| Max output | 128,000 tokens | 128,000 tokens |
| Input price | $10 / million tokens | $10 / million tokens |
| Output price | $50 / million tokens | $50 / million tokens |
| Cached input price | $1 / million tokens | $0.25 / million tokens |
| Available on | ChatGPT, OpenAI API, Azure, AWS Bedrock | Claude.ai, Claude API, AWS, Google Cloud, Microsoft Foundry |
| Standout strength | Computer use, math/science, token efficiency | Independent reasoning/coding-agent scores, cheaper long-context caching |
Pricing and Context Window
Both models charge identical headline rates: $10 per million input tokens, $50 per million output tokens. The real gap is in caching, which matters most for coding agents that resend large context on every turn. Astra’s cached input costs $1.00 per million tokens (a 90% discount off standard), plus $12.50 per million for cache writes. Fable 5.1 cut its cached-input price 75% to $0.25 per million — four times cheaper than Astra. Anthropic says this drops total costs roughly 25% for typical workloads and up to 45% for heavily agentic ones versus the earlier Fable 5.
Context favors Astra slightly: 1.05 million tokens versus Fable 5.1’s widely reported ~1 million, with both capping output near 128,000 tokens. One catch: Astra bills prompts over 272,000 input tokens at double the input/cache rate and 1.5x the output rate for the whole request. Fable 5.1 has no published equivalent surcharge, which can make it cheaper for very large documents or codebases.
Benchmark Comparison
| Category | GPT-6 Astra | Claude Fable 5.1 | Lead |
|---|---|---|---|
| Math and abstract reasoning | 97.6% on FrontierMath Tier 4 99.9% on ARC-AGI-3 96.0% on GPQA Diamond | 87.8% on FrontierMath Tier 4 Fable 5.1 wasn’t scored on ARC-AGI-3 93.7% on GPQA Diamond | Astra |
| Reasoning with tools | 57.2% on Humanity’s Last Exam with tools | 65.0% on Humanity’s Last Exam with tools | Fable 5.1 |
| Agentic coding | 57.9% on Terminal-Bench 4.0 | 55.8% on Terminal-Bench 4.0 73.4% on Anthropic’s CursorBench 3.2.0 | Astra* |
| Business and research agents | 41.4% on AutomationBench 64.6% on Terminal-Bench-Science 0.1 | 31.4% on AutomationBench 52.6% on Terminal-Bench-Science 0.1 | Astra |
| Cybersecurity | 100% on ExploitBench | Anthropic doesn’t publish a comparable score since Fable 5.1 redirects exploit-development requests elsewhere. | Astra |
| Independent testing | 61.2 on Artificial Analysis Intelligence Index | 65.7 on Artificial Analysis Intelligence Index | Fable 5.1 |
Neither company ran a shared benchmark suite, so treat these as directional rather than perfectly apples-to-apples.
*Agentic coding lead is based on Terminal-Bench 4.0; Astra was not part of the CursorBench 3.2.0 comparison.
Safety and Guardrails
Both companies frame this release around risk as much as capability. Astra is the first OpenAI model to cross the “Critical” cybersecurity threshold, so OpenAI added misalignment monitoring, stricter Codex approval flows, and refusals for advanced exploit-generation requests.
Anthropic takes a redirect-based approach instead: Fable 5.1 routes risky cyber and biology requests to its Opus models rather than answering them directly, and Anthropic’s updated safeguards cut false-positive refusals by 60% for cyber queries and 85% for routine biology questions compared with the previous version. Both companies are also building enterprise data controls: OpenAI’s Zero Data Retention for eligible API customers, and Anthropic’s Enterprise Frontier Safeguards, which keep monitoring data on infrastructure the customer controls.
Which One Should You Choose?
- Choose GPT-6 Astra if you rely on computer-use automation, heavy math or scientific computation, multimodal input (text plus images), or need the largest available context window.
- Choose Claude Fable 5.1 if you run long, cache-heavy agent loops, want lower costs on context-heavy coding sessions, or need Anthropic’s newer enterprise data-residency options.
- For general knowledge work, both perform well; the deciding factor is often your existing platform and how much of your workload depends on cached context.
Quick Checklist
- Does your workload reuse large context on every call? Fable 5.1’s cheaper cache reads may cut costs significantly.
- Do you need image input alongside text? Confirm Astra’s multimodal support fits your pipeline.
- Regularly sending prompts over 272,000 tokens? Factor in Astra’s long-context surcharge first.
- Working on math-heavy or scientific tasks? Astra’s FrontierMath and GPQA scores are the stronger fit.
- Already committed to a cloud platform? Both models are available across major providers, so this may not decide it.
Final Thoughts:
GPT-6 Astra and Claude Fable 5.1 arrived days apart, and the data shows a genuine split rather than one model winning everything. Astra’s edge in math, computer use, and cybersecurity capability is real and well-documented by OpenAI’s own testing. Fable 5.1’s edge in independent reasoning benchmarks, cache economics, and long-horizon coding reliability is equally well supported. This rivalry isn’t just academic — competition between OpenAI and Anthropic is one reason tech stocks and semiconductor demand have stayed in the spotlight through 2026. The better question isn’t which model is “best” — it’s which one matches your workload, your cached-context budget, and how much each company’s safety approach matters to you.
OpenAI, “Safety overview: GPT-6 Astra”
Anthropic, “Introducing Claude Fable 5.1 and Claude Mythos 5.1”
OpenRouter, GPT-6 Astra model pricing page
OpenRouter, “Claude Fable 5.1 pricing and benchmarks”
FAQs
Is GPT-6 Astra better than Claude Fable 5.1?
Neither wins every category. Astra leads math, computer use, and cybersecurity benchmarks; Fable 5.1 leads the independent Artificial Analysis Intelligence Index and Humanity’s Last Exam with tools.
What is the context window of GPT-6 Astra vs Claude Fable 5.1?
Astra supports 1.05 million tokens; Fable 5.1 is widely reported at around 1 million. Both cap output near 128,000 tokens.
How much does GPT-6 Astra cost compared to Claude Fable 5.1?
Both charge $10 per million input tokens and $50 per million output tokens. The gap is caching: Astra’s cached input is $1.00/million versus Fable 5.1’s $0.25/million.
Is GPT-6 Astra safe to use?
OpenAI classifies it as “Critical” risk for cybersecurity under its own framework and added monitoring and refusal systems around exploit-related requests, while keeping it broadly available through ChatGPT and the API.
Which model is better for coding, Astra or Fable 5.1?
Scores are close on shared benchmarks like Terminal-Bench 4.0, with Astra slightly ahead. Anthropic’s CursorBench results show Fable 5.1 improving over its predecessor and beating Opus 5, though it wasn’t tested against Astra there.

Pingback: What is Claude Fable 5.1? Features, Cost & Access (Guide 2026)
Pingback: Will Semiconductor to OmniVision Group – Name Change Explained (2026)
Pingback: Why Did OpenAI Delay GPT-6 Astra? The Cybersecurity Risk Explained